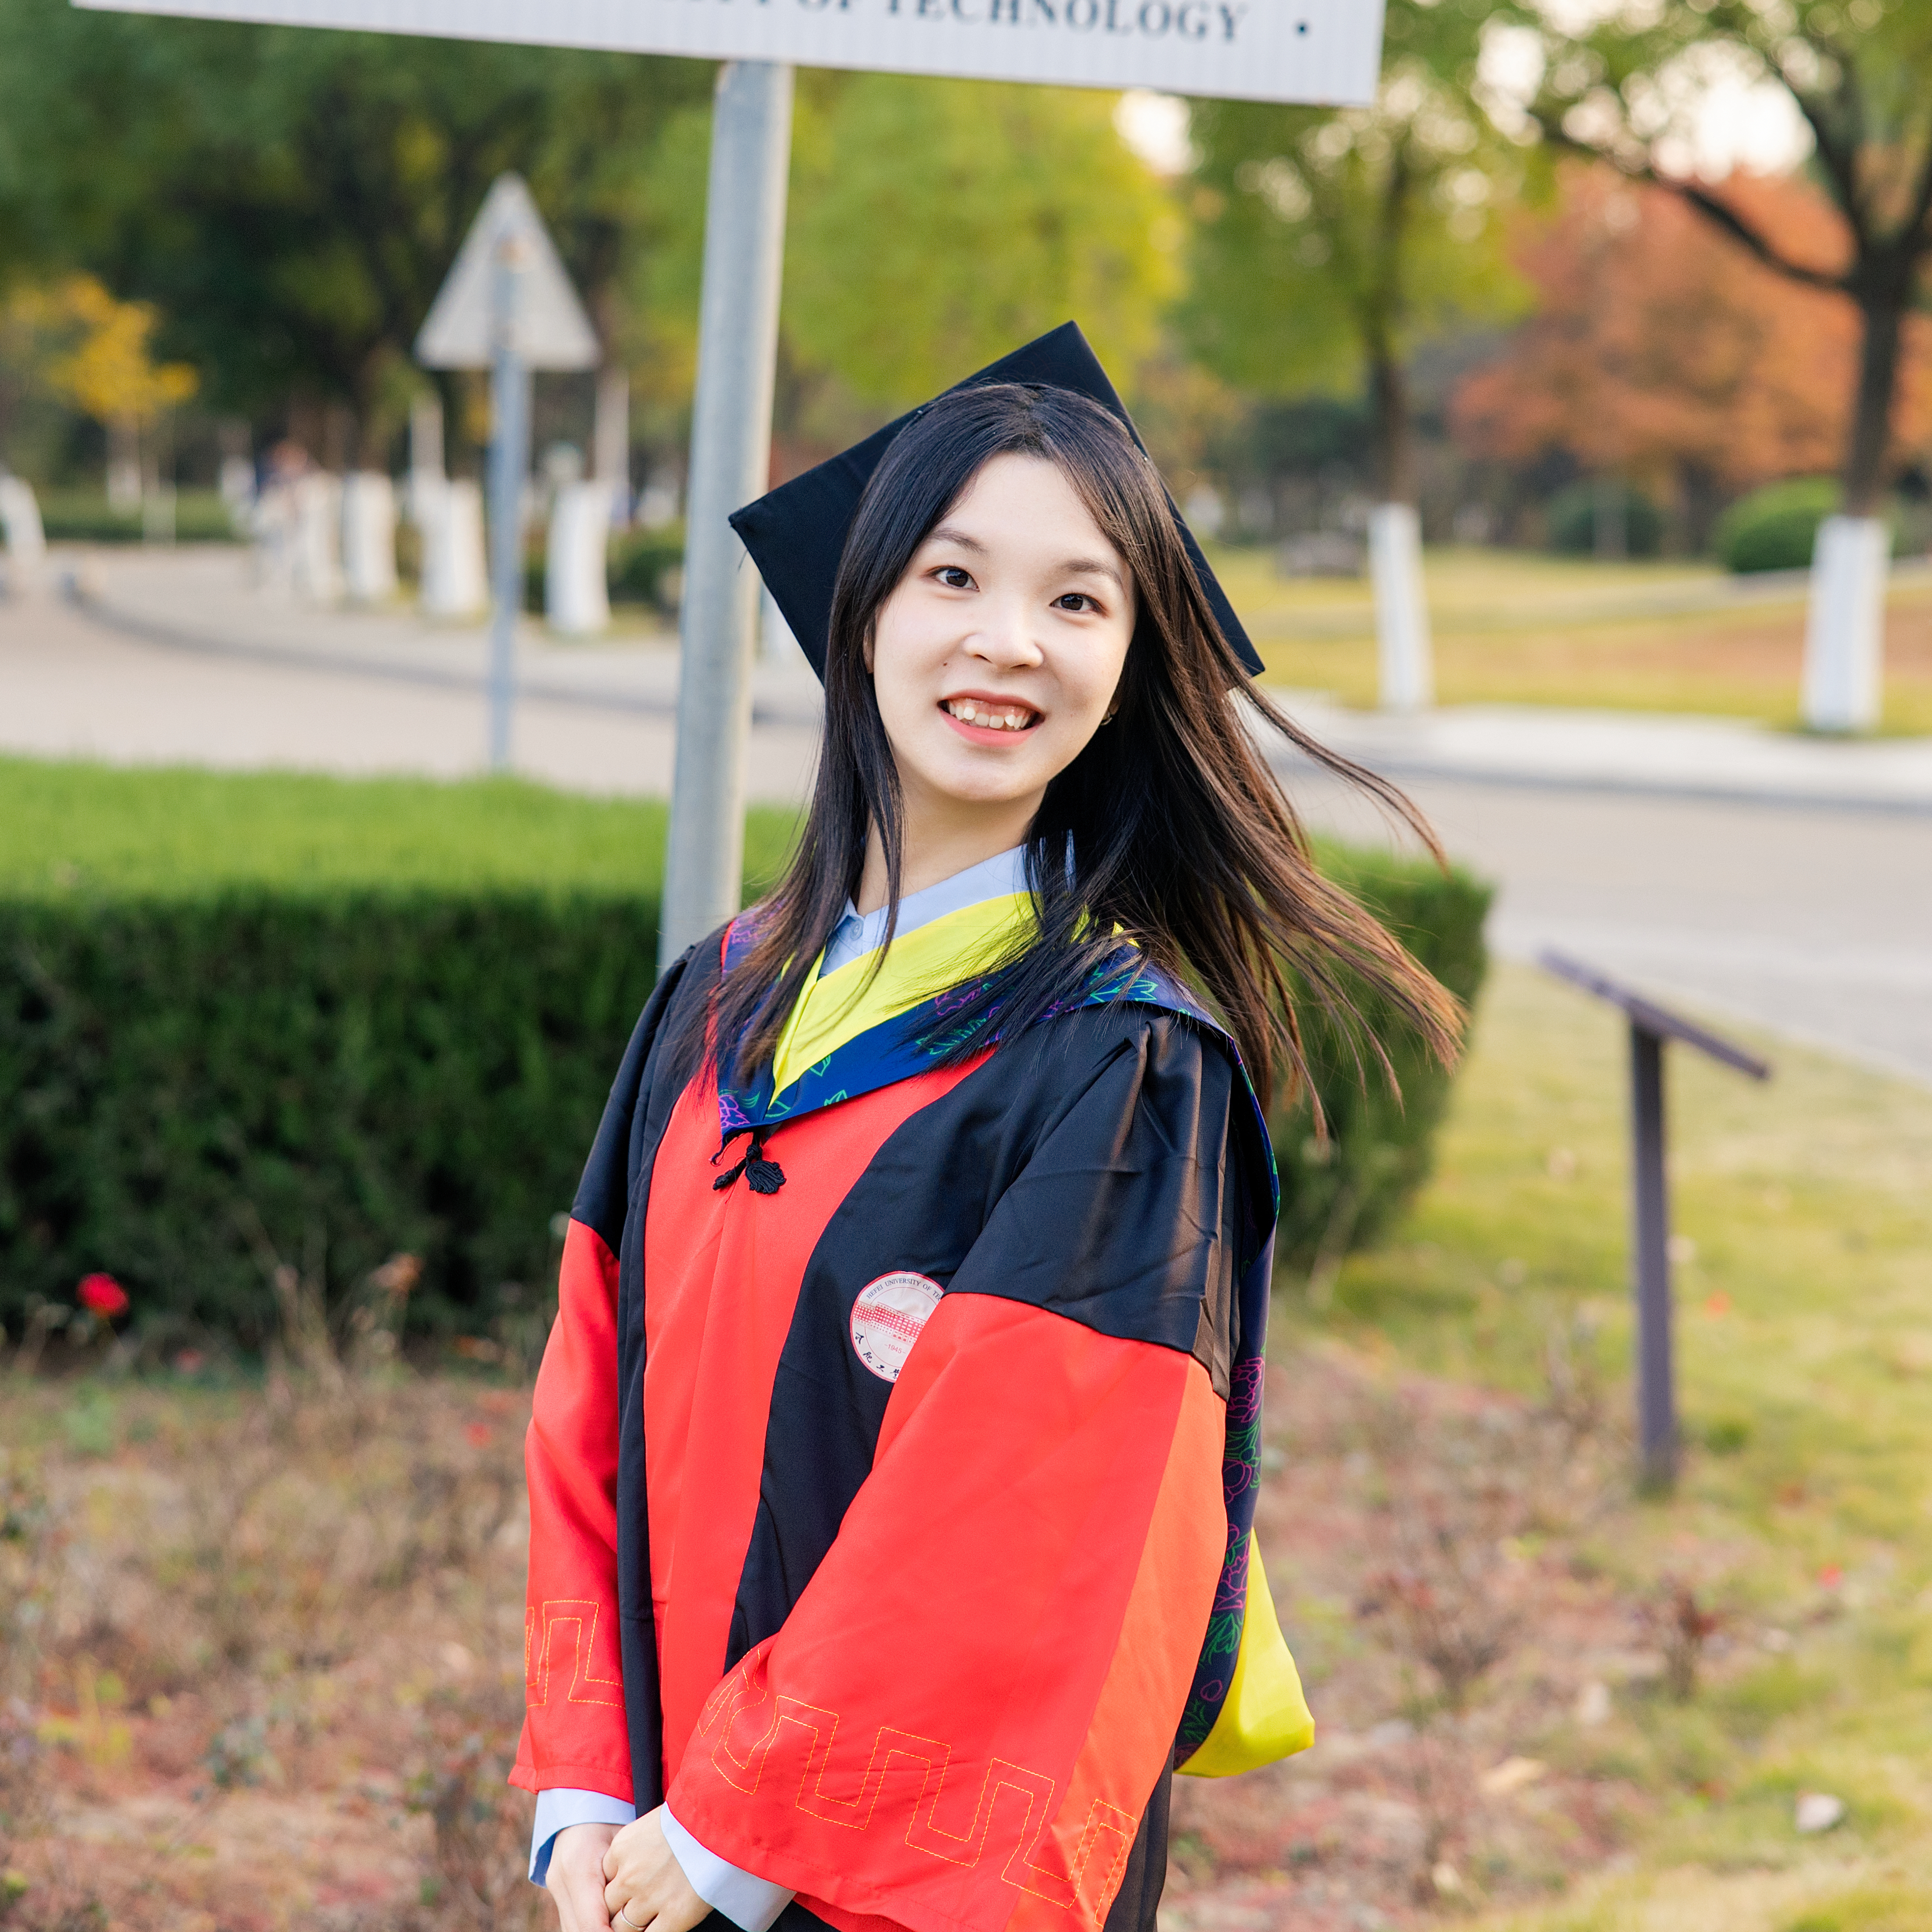
Sheng Zhou (周晟)
About Me
- I am currently a Postdoctoral Fellow at King Abdullah University of Science and Technology (KAUST) from Mar. 2026 to the present, working with Prof. Yanda Meng.
- From Sep. 2024 to Aug. 2025, I studied at National University of Singapore (NUS) as a visiting student under the guidance of Dr. Junbin Xiao, Prof. Angela Yao, and Prof. Tat-Seng Chua.
- From Aug. 2023 to Aug. 2024, I studied at University of Science and Technology of China (USTC) for one year under the guidance of Prof. Xun Yang.
- I obtained my Ph.D. degree in Computer Science at Hefei University of Technology (HFUT) through a direct M.S.–Ph.D. program from Sep. 2020 to Dec. 2025, supervised by Prof. Meng Wang and closely collaborated with Prof. Dan Guo.
Research
My research focuses on developing AI systems that can understand complex visual environments and effectively bridge vision and language. My research interests include Video Understanding, Visual Question Answering, and Visual Grounding.
I currently focus on Video Understanding and Multimodal Large Language Models (MLLMs) for real-world and healthcare applications, with an emphasis on efficiency, interpretability, and trustworthy AI. My goal is to build intelligent systems that can perceive and reason about the real world, support human decision-making, and enable effective human–AI interaction.
I am actively seeking Research Interns and Visiting Students with backgrounds in Computer Vision, NLP, or Multimodal Learning.
News
- [Jul. 2026] Invited as Area Chair for the Multimodal Large Language Models for Unified Comprehension and Generation (MUCG) Workshop at ECCV 2026.
- [Jun. 2026] One paper is accepted by ECCV’26. 🎉
- [Apr. 2026] Invited as Area Chair for the Any-to-Any Multimodal Learning (A2A-ML) Workshop at CVPR 2026.
- [Feb. 2026] One paper is accepted by CVPR’26. 🎉
- [Nov. 2025] Successfully defended my Ph.D. 🎓 Thesis: Research on Scene Text-Driven Visual Question Answering.
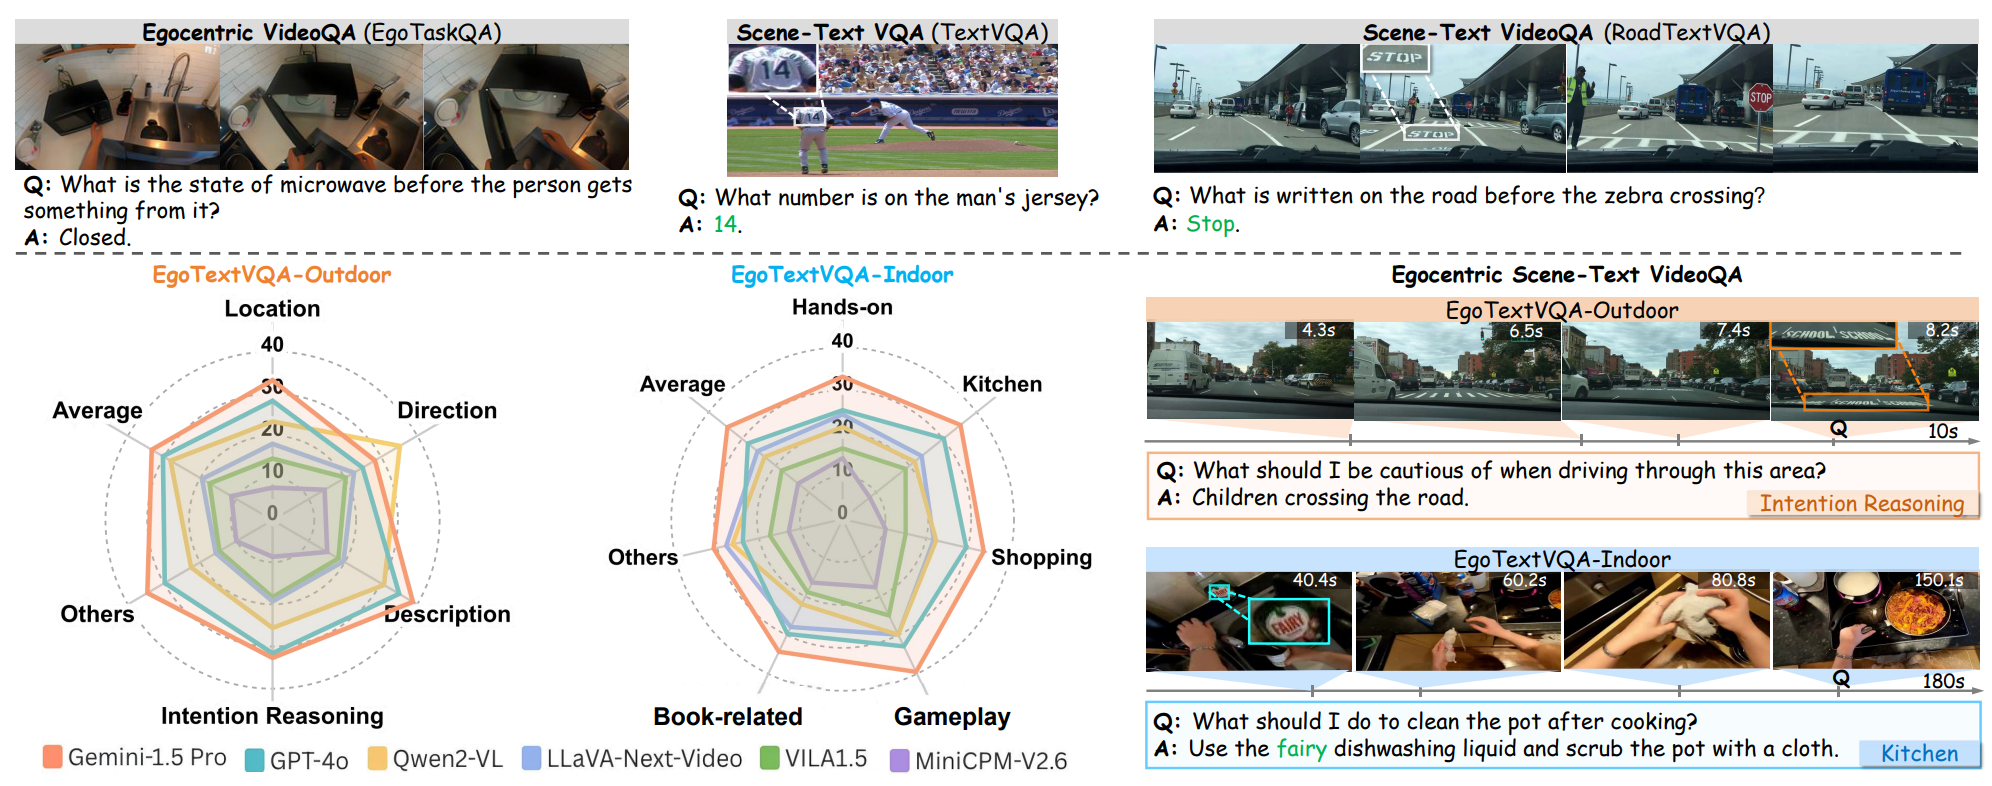
- [May. 2025] Our work EgoTextVQA will be presented at the Egocentric Vision (EgoVis) Workshop and Vision-based Assistants in the Real-World (VAR) Workshop @ CVPR 2025!
- [May. 2025] One paper is accepted by IEEE TMM’25. 🎉
- [Feb. 2025] One paper is accepted by CVPR’25. 🎉
- [Feb. 2025] I am honored to receive the Tat-Seng Chua Scholarship.
- [Sep. 2024] I will be a visiting student at NUS for one year, collaborating with Dr. Junbin Xiao.
- [Jan. 2024] One paper is accepted by ACM TOMM’24. 🎉
- [Sep. 2023] One paper is accepted by IEEE TIP’23. 🎉
- [Jul. 2023] Started a study at USTC supervised by Prof. Xun Yang.
Publications
* Equal contribution; # Core contributor; † Corresponding author
-
 ECCV
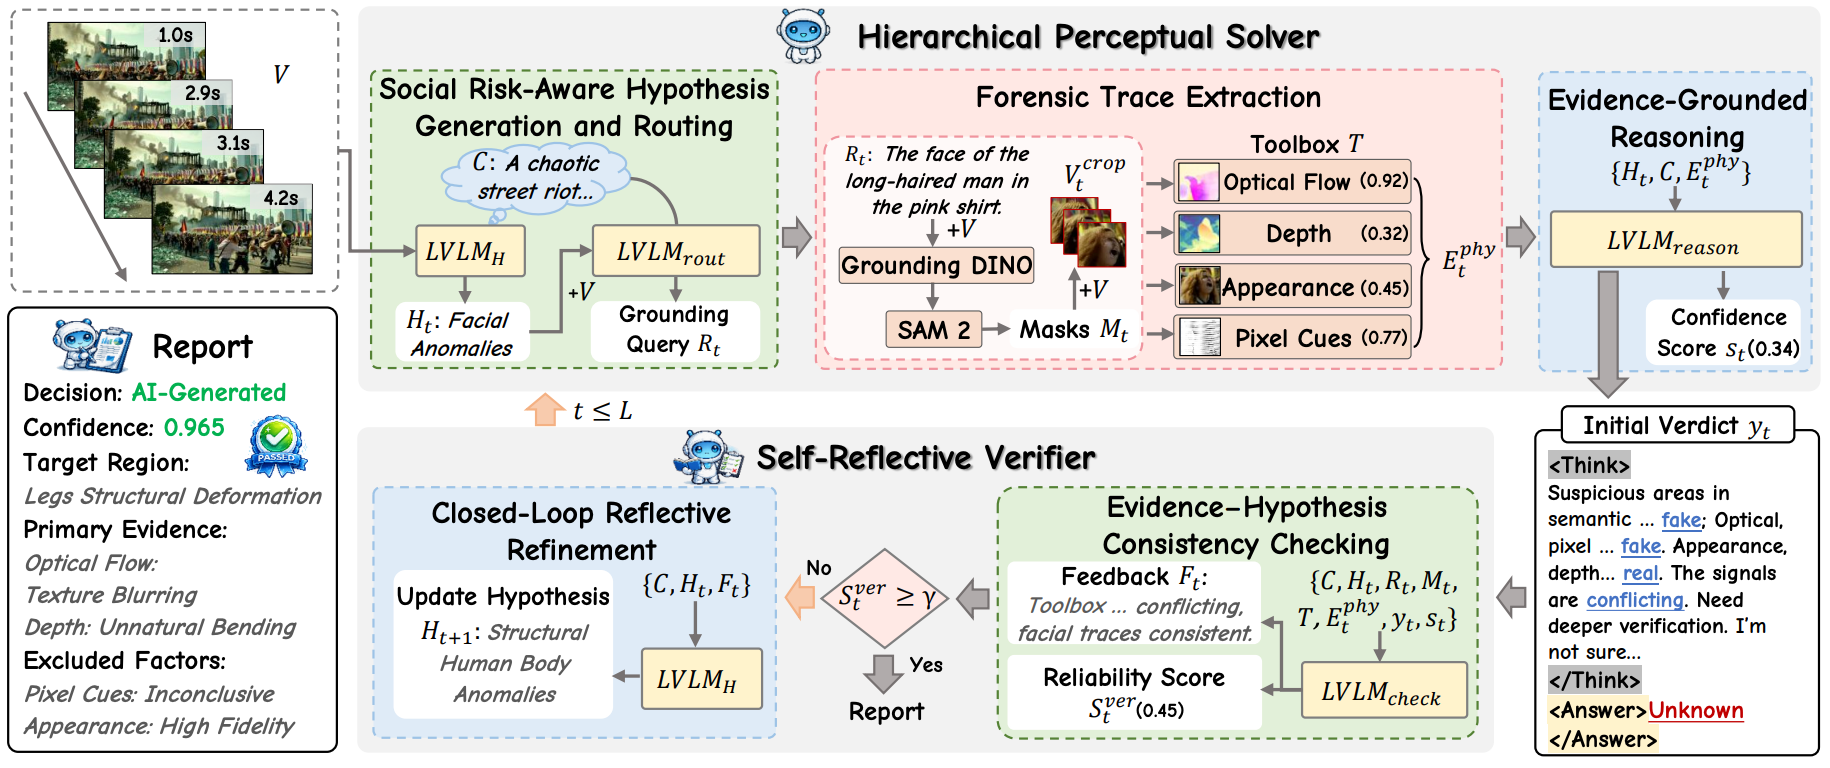
SafeGuard: A Multi-Agent Perception-Reasoning Framework for Social-Risk AI-Generated Video DetectionEuropean Conference on Computer Vision (ECCV), 2026.
-
 CVPR
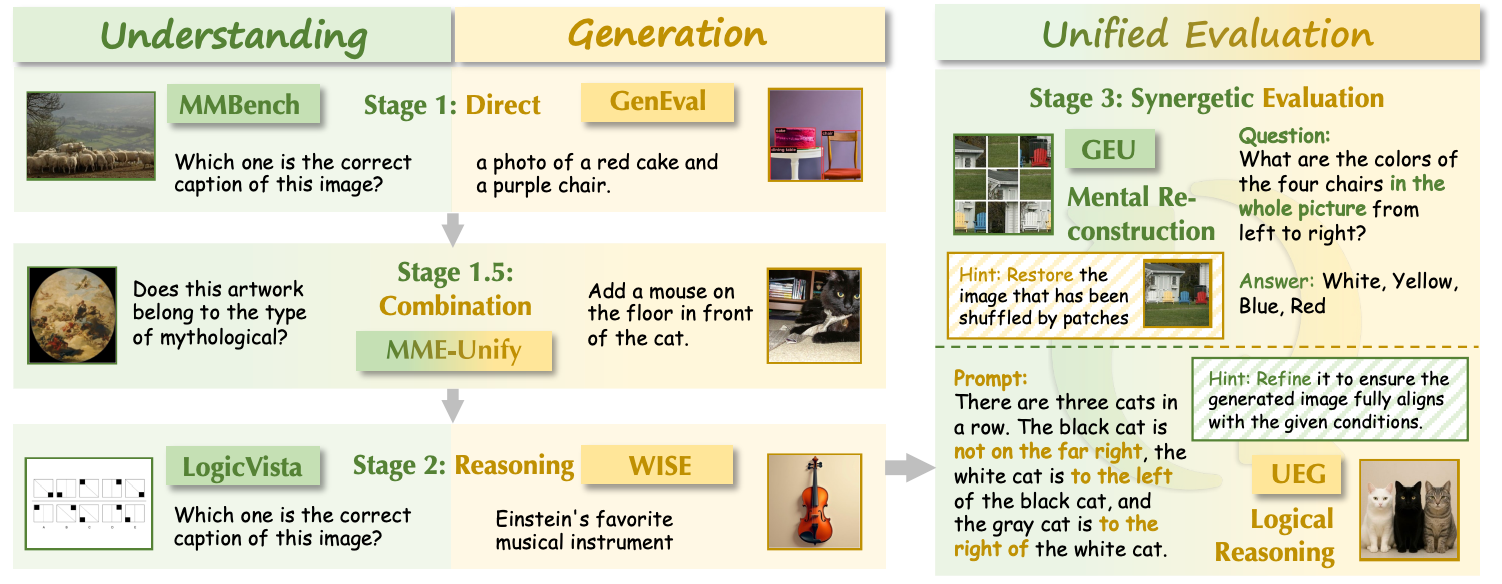
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026.
-
 CVPR
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025.
-
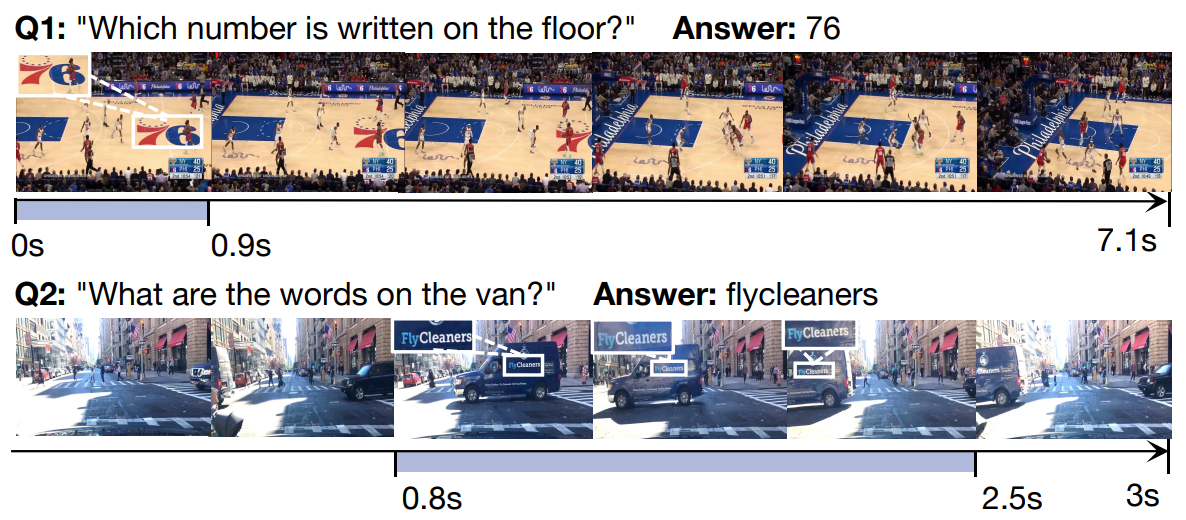 TMM
IEEE Transactions on Multimedia (TMM), 2025.
-
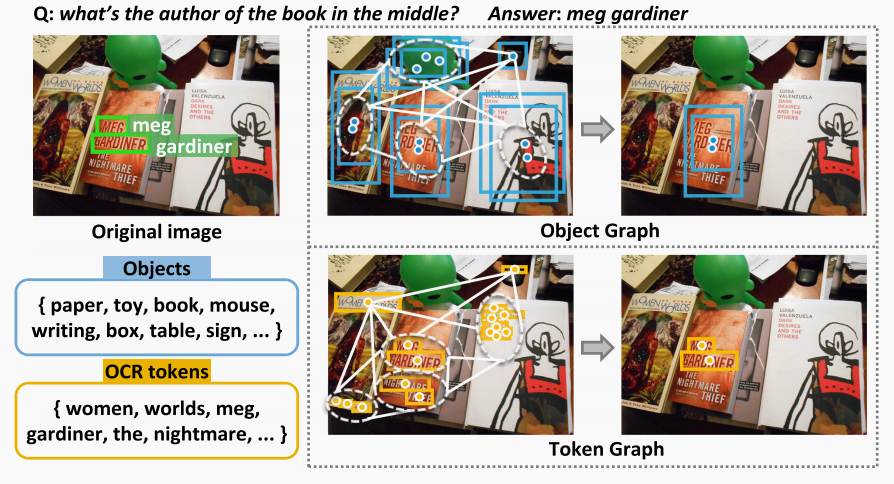 TOMM
ACM Transactions on Multimedia Computing, Communications and Applications (TOMM), 2024.
-
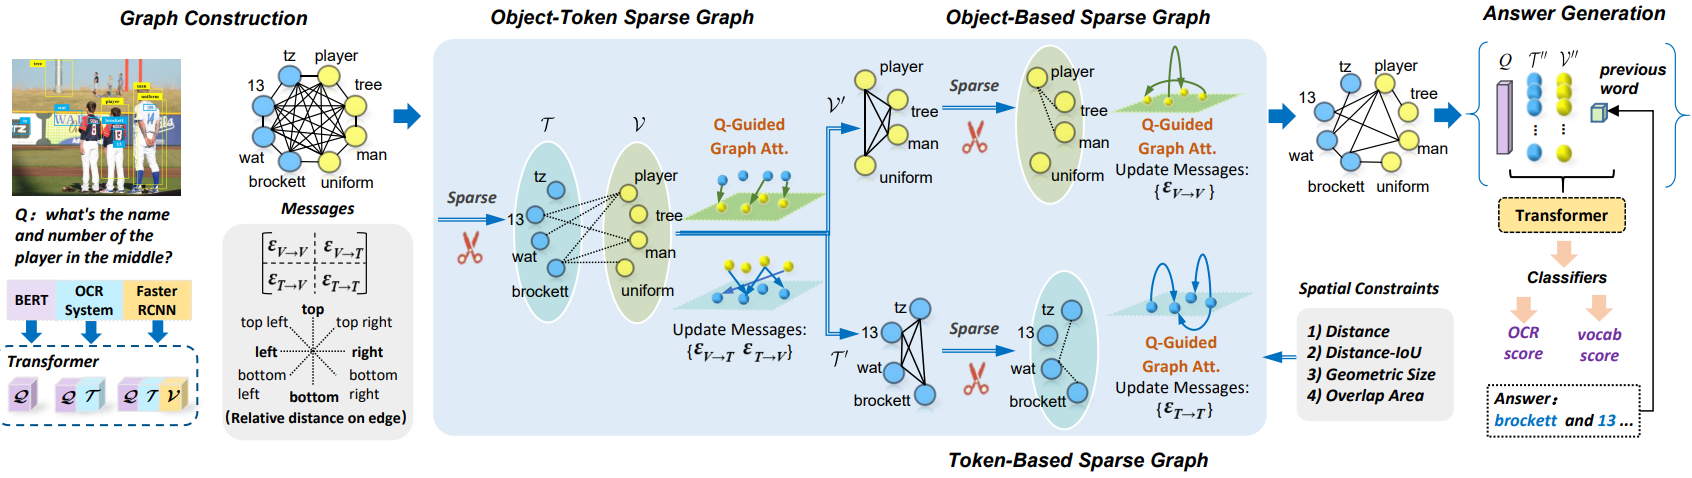 TIP
IEEE Transactions on Image Processing (TIP), 2023.
Services
- Area Chair: MUCG Workshop @ ECCV 2026 · A2A-ML Workshop @ CVPR 2026
- Conference Reviewer: NeurIPS 2026 · CVPR 2026 · ECCV 2026 · ACM MM 2025, 2026 · EMNLP 2026 · AAAI 2027 · IJCNN 2025, 2026, 2027
- Journal Reviewer: IEEE TIP · IEEE TCSVT · ACM TOMM · Information Fusion · Pattern Recognition · Neurocomputing · JKSU-CIS
Selected Honors and Awards
- [2025.02] Tat-Seng Chua Scholarship
- [2022 - 2025] First Class Academic Scholarship (three times)
- [2020 - 2022] Second Class Academic Scholarship (two times)
- [2020] Outstanding Graduate of Innovation and Entrepreneurship in Hunan Province
- [2016 - 2019] National Encouragement Scholarship (three times)
Last updated: 2026.10
Powered by Jekyll and Minimal Light theme.